A Company Brain Example: The One That Runs My Company
A company brain is one place where AI can read your company’s email, call transcripts and documents, and answer questions with a link to the source (the longer definition, with its parts).
My company runs on one git repository. It holds every client folder, every call transcript we’re allowed to keep, a few thousand email syntheses, and a set of Claude Code commands that read all of it. When my co-founder asks “what did we promise this client about hosting?”, the answer comes back with a link to the email or the transcript line where we said it. That repository is our company brain.
I’m writing this down because a lot of what gets sold as AI memory for work is one person’s notes app with a chatbot on top. That is useful. It’s also a different thing from a system that two founders, a handful of engineers and a rotating cast of contractors all lean on at once.
What’s in the folder
The layout is boring on purpose. Every client gets a folder at clients/<firm>/<engagement>/. Inside: a CLIENT.md with contacts and context, a MEMORY.md that acts as a rolling relationship memory, syntheses of emails and meetings, a machine-generated index, and a references/ folder with the raw transcripts and emails. There are about 65 live firm folders right now (three of them internal projects) and 34 archived ones.
Next to clients/ sit the departments: sales, project management, finance, strategy, marketing, ops, automations. A lib/ folder holds 29 shared Python modules for things like branded email and PDFs. All of the Claude Code tooling lives in one .claude/ folder at the root: 67 commands, 72 skills, 18 agents and 26 guides (what the commands do, department by department).
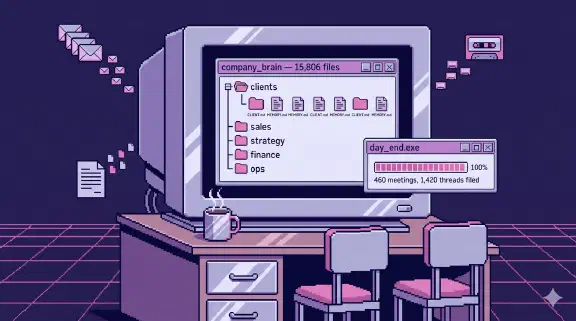
The brain itself is mostly markdown. Out of 15,806 tracked files, 6,010 are markdown, including 727 transcripts and 1,295 emails. Claude reads those files the same way a new hire would, starting from the 20 CLAUDE.md files that explain each part of the repo. The root one was 58 lines in early March and is 223 lines today, and most of those lines are there because something went wrong without it. When we brought on three people in August and September, the AI wrote their onboarding kits from the same files.
How things get in
A brain that depends on someone remembering to paste things into it stays empty. Ours is fed on a schedule (how the email part works). About a dozen Cloud Run jobs sync email three times a day, pull meeting transcripts every hour, post standups and check time logs. Transcripts go through a confidentiality gate before they touch the repo, and I learned why that gate has to be a required check the hard way (the day 46 transcripts reached main).
The other half is a command each founder runs at the end of the day. /strategy:day-end-process is about 1,100 lines of instructions plus nine guides and six agents. It reads the day’s meetings and email, files what matters into the right client folder, drafts replies (as drafts, never sent, for reasons), proposes tasks, suggests doc edits and captures lessons. It’s the closest thing we have to a chief of staff, and how it compares with Claude Duet has its own post.
Between June 4 and September 30 it ran 39 times across two founders. In that window it processed 460 meetings and 1,420 email threads, surfaced 626 threads where someone owed a reply, made 303 doc edits, synced 270 contacts and researched 57 companies. It also created 1,042 tasks, which was far too many, and fixing that took a script rather than a better prompt (the full story).
How it grew
It didn’t start as a brain. In late December 2025 I wrote a few business commands: one to verify docs, one to find gaps in a proposal, one to synthesize a client’s emails. On March 5, 2026, I pulled the scattered projects into one monorepo, archived 21 stale projects, and un-archived 4 of them the same day when it turned out people still used them. The next day I consolidated every workspace’s .claude folder at the root and archived 7 more.
On May 1 all client work moved into clients/<firm>/<engagement>/. That one reorganization was followed by about ten commits fixing broken paths, which is the real cost of restructuring something that a lot of automation reads. The same day we deleted 12 project-management commands nobody ran and a 23-template email skill (we’ve deleted 52 skills and commands so far).
June brought the six-agent day-end pipeline and rules for where files are allowed to live, checked by a PreToolUse hook that can block a write before it happens. July added the knowledge layer: a log of rulings, a learnings store, a small wiki and managed search. August through October has been mostly reliability work, which is less fun to write about and more important.
The repo has 3,474 commits and pull requests past #685. 2,978 of those commits (86%) carry a Claude co-author line, across ten model versions. Commits peaked at 550 in March, the month of the big consolidation.
Show the data
| Month (2026) | Commits |
|---|---|
| March | 550 |
| April | 450 |
| May | 427 |
| June | 358 |
| July | 331 |
| August | 362 |
| September | 251 |
| October 1 to 14 | 98 |
Company brain versus personal brain
This is the part that separates a company brain from a personal one, and it’s where most of the design effort went. (If you’re starting from a personal one, here’s what changed when ours got a second writer.)
Claude Code keeps a private memory per user. Anthropic’s docs say auto memory is machine-local and its files are not shared across machines, while a project CLAUDE.md is shared with the team through version control. When we started logging company rulings in July, six of the first ones were copied straight out of one person’s private memory files, including the rule that the AI never sends client email. Those rules had been governing that person’s sessions and nobody else’s. Anything a team depends on has to live somewhere the whole team reads, with a history, so now rulings go in one append-only log. Anthropic’s Claude Duet is a personal brain too, one that can sign in to company accounts from a personal plan, which is why I wrote a connector policy before anyone connects the books.
Two founders also means two mailboxes, two calendars and the same client meeting showing up twice. Without coordination, both day-end runs would file the same transcript and mint the same tasks. The fix was a shared coverage table with keys that match across accounts, plus one hard rule: my partner filing an email does not cancel my obligation to answer it (details here).
Then there’s the setup problem. People on the team have very different technical backgrounds, so in July we made a ruling: anyone using the brain needs git, Claude Code, uv and the shared environment file, and nothing else (what that looks like for non-developers). Heavy work runs remotely. That ruling killed a local semantic search setup that needed about 2GB of models on every machine. We also rejected an option where every search query was a paid model generation. We ended up on Vertex AI Search (Google is renaming it Agent Search), which only does retrieval (it can return matching chunks instead of a generated answer), costs somewhere between $0 and $6 a month, and indexed 1,365 documents. On two of our three test queries, plain grep found nothing at all, which settled the question of whether search was worth adding.
People also leave. A team brain has to know who has access to what, so the repo keeps an access registry with 39 pages, one per platform, and CLAUDE.md tells Claude to ask about updating it whenever a new tool or credential comes up in conversation. When two contractors left this month, the offboarding was a checklist against those pages instead of an exercise in memory. Who holds which login is one of five places our tribal knowledge hid, along with a finance README that said 73 vendor rules when the file had 151.
What doesn’t work yet
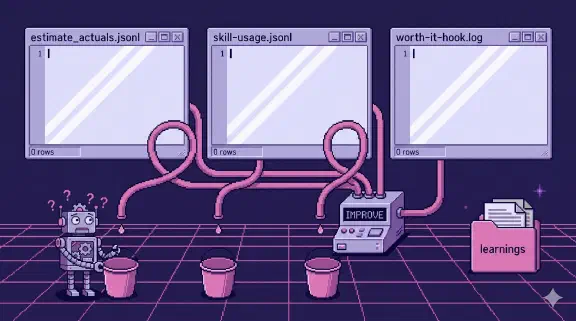
Plenty. We built an estimate calibration engine that is supposed to learn from estimates versus actuals. It has zero rows of actuals. We built a hook to track which skills get used. Its log file has zero lines. Collecting the data turned out to be the hard part, and I wrote about that in three feedback loops that collected nothing. Automation has its own costs: a nightly routine and an AI reviewer once argued on a pull request for 21 hours, and our build gate now starts by asking whether the thing should exist at all.
We tested a knowledge graph properly and killed it, because two identical runs agreed on only 16% of node labels (the test). And the tools feeding the brain lie in small ways: transcription that hears a person’s name as a common word, a notes tool that returned a months-old meeting byte for byte, a Notion integration that couldn’t see 19 of 36 databases for months without anyone noticing (a list of them).
None of this makes the brain less useful day to day. It does mean the honest pitch for a company brain is “it answers questions about your company with sources,” and the claim that it compounds on its own needs a lot more evidence than I’ve got.
If you’re starting one
Start smaller than this. Most people start by uploading files to a custom GPT or a Project, which is fine for one person and goes stale for a team (the four ways to give ChatGPT your data, compared). For a team, start with one folder per client, email and transcripts syncing in on a schedule, one log for decisions, and a CLAUDE.md that tells the AI where things are. That alone answers most of the questions people actually ask. Everything else in this post got added because a specific thing broke. Your SOPs can come later, and the AI can draft them from what actually happened.
The quickest way to see what this feels like is the demo: a made-up agency’s email, calls, docs and spreadsheets, and a brain you can race to the answer. If you want a plan for your own tools first, the setup planner asks six questions and gives you one for free. If you want one for your own team, I set it up on standard Claude Team, from $3,997 for one team of up to 20. One job live on your real work by day 14, or all your money back. If you’re comparing builders, I priced what 56 freelancers charge and what to ask them.