Self-Improving AI: Our 3 Feedback Loops Collected Nothing
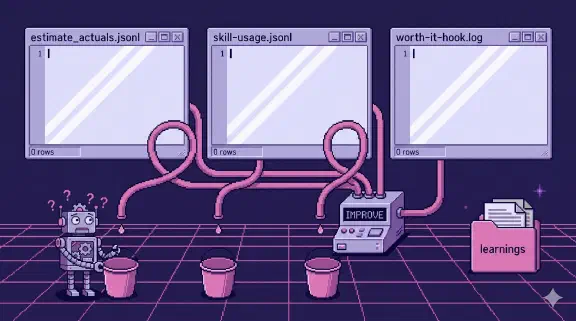
In August we built three ways for our company brain to learn from its own work: an estimate calibration engine, a log of which skills get used, and a hook that asks “is this worth building?” before we build something. Two months later the calibration store has zero rows, the usage log has zero lines, and the hook never fired once on the day it went live. Meanwhile, the one loop our planning doc described as fully closed turned out never to have run at all.
I’m writing this up because “the AI learns from you and improves over time” is in a lot of pitches right now, and I’ve spent most of a year building a system that’s supposed to do that. Most of the time it doesn’t, and the reasons turned out to be more mundane than I expected.
The table that admitted it
Back in May we wrote a vision doc for how the company should run. Section 5a split every automated loop into three parts. Capture means a sensor reads what happened. Route means the output reaches the right person. Improve means the system itself changes because of what it captured.
Then it listed a dozen of our loops in a table with a column for each. Capture was “YES” all the way down. Route was nearly all “YES.” The Improve column was almost entirely “NO,” with one “PARTIAL” and a few loops marked as closed only within their own little function. The doc’s own test for health was blunt: if improvements only happen when one of the founders notices something, the loop is still open.
One row had “YES” in all three columns: the marketing loop. Competitor data in, a three-agent analysis, a weekly plan, posts published, performance tracked, next week informed. The doc called it the working template that every other loop should copy.
In September we audited our scheduled jobs. Cloud Scheduler had 11 live jobs. Our docs described 20 endpoints. Eight of the documented jobs had a documented schedule, a monitoring entry or a README section, and in three cases a line in our operating-rhythm doc calling them running automation. Cloud Run request logs showed that none of the eight had ever received a single request.
The marketing feedback loop, the template every other loop was supposed to copy, was one of them.
Two bugs made sure they couldn’t have worked even if someone had scheduled them. Two depended on a CLI that wasn’t installed in the container. Six had their route prefix applied twice, so the documented URL would have returned a 404. And our monitoring tool creates a monitor the first time a job checks in (Sentry’s SDK creates the monitor on its first check-in if it doesn’t exist yet), which means a job that never runs never gets a monitor, and nothing ever alerts. We retired all eight and wrote a RETIRED.md explaining what each did and what a rebuild has to fix first.
Loop one: estimate calibration
This one is the most carefully designed and the most empty. The idea: every time an engagement closes, record what we estimated and what it actually took. Regenerate multipliers per category and size band. Only let a multiplier override the default contingency once there are at least three data points for that band. Keep a “golden set” of five to ten closed engagements and replay every proposed calibration against them. A change that makes the replay less accurate doesn’t merge.
I still think that design is right. The golden set file has one row, and the engagement column says “TBD.” The actuals log has zero lines.
The engine depends on two things happening. Someone runs a backfill command against past engagements, and every closed engagement goes through a retrospective step that writes its actuals. Neither of those is part of anyone’s week. The engine was built, tested, and wired into the weekly review, which now honestly prints “no data” for calibration drift. It’s been printing that since August.
Loop two: skill-usage telemetry
We have dozens of skills and commands. I wanted to know which ones get used and which ones nobody touches, so a hook appends a line every time a skill runs, and the weekly review shows the top five and the never-used list. (That list is what you need when it’s time to delete the skills nobody uses.)
It’s been live since August 20. The log has zero lines.
The hook’s own header was honest about its limits from the start: it only sees skills invoked through the skill tool, not slash commands someone types, and it records invocation, not outcome. What it didn’t anticipate is that it may not see anything. It reads its input from an environment variable only, with no fallback to stdin. That’s exactly the first bug we found in loop three.
Loop three: a Claude Code hook that never fired
If your Claude Code hook isn’t firing, check that it reads its JSON input from stdin. That was the first of three bugs in the hook below.
The worth-it check asks whether something should exist before we spend time automating it (more on that in Before Automating Something, Ask Whether It Should Exist). The hook’s job was to notice when a session starts building new capability and suggest running the check.
It never fired in the day it was live. The rewrite’s docstring lists three independent reasons:
- It only read hook input from an environment variable. Claude Code delivers it on stdin. So it exited early on every single tool call.
- It only watched the Write and Edit tools. A session that wrote files through a shell heredoc was invisible to it. Our folder-rules hook had hit the same blind spot earlier, when agents it blocked started writing files through the shell instead.
- It didn’t treat the
plans/folder as a sign of new capability. So even with the first two bugs fixed, it would only fire once code was being written, after the decision to build had already been made.
The third one is the bug I find most instructive. Even working perfectly, the hook was aimed at the wrong moment.
The Python rewrite fixes all three, and it ships muted. It records what it would have fired on, so we can read a week of would-have-fired lines before it interrupts anyone. A hook that fires every session becomes wallpaper, and that’s the exact failure the worth-it check exists to prevent.
The check itself works fine when a person runs it. Its ledger has two entries, both run by hand in September. The first one said not to build a small reminder job, and the evidence it cited was the eight scheduled jobs that had never received a request.
Silence looks like a quiet week
Every one of these failures had the same shape. An empty log looks identical to a week where nothing happened. A monitor that never checks in looks identical to a job that never fails.
We kept hitting versions of this outside the feedback loops too. An integration shipped with 153 passing tests over a broken feature. A code review workflow we built “refuted” 10 out of 10 findings, and hand-checking showed at least three were real bugs. The refuter had been told to default to refuted, and it could always retreat to “that’s cosmetic.” After a hosting move, a scheduled keepalive returned a 405 every day because the new scheduler sends GET and the route only accepted POST. A manual test with POST had masked it.
What we changed is unglamorous. A scheduled job only counts as working once the scheduler’s own logs show it running, never because a manual call succeeded. That evidence costs nothing to collect, since Cloud Scheduler writes a log entry at the start and end of every execution. Tests for an integration get mutation-tested: put the defect back and confirm the suite actually fails. The weekly review prints “no data” or “not measurable” instead of leaving a line out, because a missing line reads as zero. Our API spend line follows the same rule, for reasons I covered in Two Bots Argued on a Pull Request for 21 Hours. And I now treat an empty store a couple of weeks after launch as a bug report.
The loops that do fill up
Two stores are growing: a decisions log with 42 rulings and a learnings file with 42 entries. Day-end alone has captured 37 learnings since late August.
| Loop, and where it writes | On October 13 |
|---|---|
| Estimate calibration, actuals log | 0 lines |
| Estimate calibration, golden set | 1 row, engagement “TBD” |
| Skill-usage telemetry, usage log | 0 lines |
| Worth-it hook, first live day | 0 fires |
| Decisions, rulings log | 42 rows |
| Learnings, learnings file | 42 entries |
The difference is boring. Both are written as a side effect of something we already do every day. Day-end runs whether or not anyone cares about learnings, and capturing one is a single extra step at a gate a human is already looking at. Decisions get logged when someone makes a ruling in a conversation that was happening anyway.
The empty loops all needed a new habit. Someone has to run the backfill, someone has to remember the retrospective, a hook has to fire at the right moment in a session. None of those had an owner, and the system had no way to notice they weren’t happening.
Even the loops that fill up don’t improve anything by themselves yet. A learning becomes a rule only after three confirmations, and skill changes arrive as proposed diffs a person merges. By the doc’s own test, most of our loops are still open. I’m fine with that. I’d rather have a system that’s honest about which half of “self-improving” it does.
Our AI bookkeeper had a loop of that kind: every correction I made became a vendor rule in a file, and there were 151 of them by the time we retired it.
If you’re evaluating anything sold as self-improving, ask to see the log it learns from and how many rows are in it. If you want a company brain built with that kind of honesty about what’s working, tell me about your team, and bring the log your current tool says it learns from.