Why AI Agents Fail in Production: 8 Times Our Tools Lied
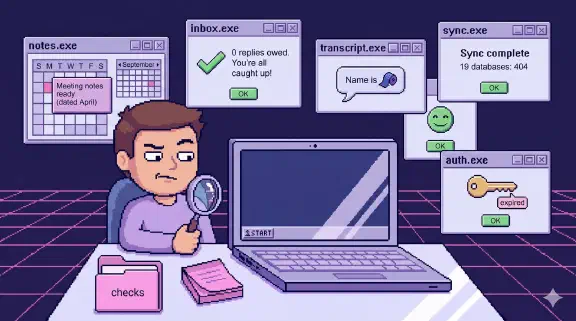
Most of the AI agent failures we’ve hit in production started in the tools feeding our company brain. The model itself caused far fewer. Transcription, email, meeting notes, the task database and authentication each returned a confident answer that was wrong, stale or empty, and none of them raised an error. Here are eight from the last few months and the check we added for each one.
Some context. Every evening, a pipeline reads the day’s meetings and email for each of the two founders, files what matters into the right client folder, and proposes tasks. Between June and September it processed 460 meetings and 1,420 email threads. At that volume, a tool that is wrong 1% of the time is wrong several times a week. The model downstream has no way to know, because the input looks normal.
1. The transcript renamed a teammate after a software company
Our meeting recorder transcribes phonetically. When it hits an unfamiliar name, it reaches for a common word that sounds close. This is a known weak spot. A 2025 paper on named entities in lecture transcription opens by noting that the error rate of the best current speech recognition “remains high for named entities,” and those are usually the words that matter most downstream. In one evening’s batch we caught three of these: a teammate’s name came out as the name of a well-known software company, a project name became a word for a kind of fabric, and a third turned into something that sounds like “after it.”
Nothing misrouted, but only because a human happened to notice. An unchecked run would have created a task assigned to someone who doesn’t exist on a project that doesn’t exist.
The check: before routing any task, unfamiliar names and project names get cross-checked against the team roster and the project list. If a name doesn’t match anything, it gets flagged instead of guessed.
2. The meeting notes were from April
One recurring meeting has notes generated automatically. On a Monday in September, the notes tool returned the notes from an April occurrence of that same meeting. Byte for byte. Recurring meetings share one calendar event, and the tool picked the wrong instance.
The summary looked plausible because it was a real summary of a real meeting with the same people. It was just five months old.
The check: hash every incoming notes export and compare it to transcripts we’ve already stored. Same hash, different date, reject it.
3. The same email conversation got a new thread
We match emails we’ve already processed by thread ID, which is the obvious key. Then we saw the same conversation show up twice with two different IDs. After a reply gap of one to three weeks, the mail provider started a fresh thread container (new root message ID too) for what any human would call the same conversation. We saw it twice in one catch-up run.
Thread-ID matching alone would have filed it again and probably created duplicate tasks, on top of the 1,042 tasks the brain was already creating. The same conversation sitting in both founders’ inboxes is its own duplicate problem, which I wrote up in Two Founders, One Brain.
The check: when a thread looks new, also compare subject, participants and the earliest message’s content against threads we already captured.
4. One call, two clients
Our pipeline sorts meetings by client before handing each one to a processor scoped to that client. It assumes one meeting maps to one client. Then an engineer used a single ad hoc call to discuss both of their active projects, for two unrelated clients, under one title.
The processor for client A would have happily created client B’s action items inside client A’s project. In a system where client confidentiality is the hard rule, that’s the bad direction to fail in. (Transcripts are also where our worst confidentiality scare came from, 46 of them in one pull request.)
The check: a client-scoped processor still reads the whole transcript, and it has to explicitly drop items that belong to a client it wasn’t dispatched for. Silent inclusion became a named exclusion step.
5. The model dropped the Fourth of July
We use a model to extract contractor hours from a log’s version history. Sonnet, which ran that job until September 2026, skipped one full day, July 4 as it happens, in a July log. The totals didn’t match the invoice, and we started a discrepancy conversation with the vendor about hours that were in the log the whole time.
This is the only one of the eight where the model itself was the tool that failed. It cost us some credibility with a vendor, which is more expensive than tokens.
The check: that extraction now runs on Opus, and any discrepancy gets reconciled against the raw source before anyone says a word to a vendor.
6. “No owed replies” meant the search was broken
One step of the evening run finds inbound email you haven’t answered yet. It searched the primary inbox category, using Gmail’s category:primary operator. On a mailbox with category tabs turned off, that search matches nothing. So the sweep only returned threads the founder had already replied to, and every never-answered inbound email disappeared. The report said, in effect, “you’re all caught up.” The same sweep surfaced 626 replies we owed over four months.
An empty result is the most dangerous output a tool can give, because it reads as good news.
The check: the script probes whether the category query works on that mailbox. If it doesn’t, it falls back to a plain inbox search and prints a note saying so.
7. Half our Notion databases had been answering 404 for months
While moving a Notion sync into a scheduled job, we ran it read-only first and found that 19 of our 36 databases returned “not found” on every request. The integration had never been shared with them. That’s how Notion works by design: a page must be manually shared with a connection before the API can touch it, and the error for an unshared page is the same object_not_found you get for a page that doesn’t exist. Their sections of our reference docs had been frozen for months, and nobody noticed because nothing ever errored loudly enough.
The check: the job now separates “failed this run” (which pages someone) from “unreachable” (a standing permissions gap, reported but not paged). Mixing the two would have meant 19 red alerts every morning, which trains everyone to ignore the alert.
8. Authentication dies every day
The Google Workspace token expires daily. (Our whole email setup, and why we read Gmail through one command-line tool, is in Can Claude Read My Email?) When it dies, every scheduled task that touches Gmail or Drive fails until someone logs in again, and the failure surfaces wherever it surfaces.
The check: a small helper detects the dead token and re-runs the login while keeping the callback listener alive, so re-auth is one click on “Allow.” It’s boring, and it removed a daily source of half-finished runs.
And one where we lied to ourselves
The tools aren’t the only liars. One integration shipped with 153 passing tests and a reply flow that returned zero results against the real API. The test fixture asserted a field value the real API never returns, and carried a field the API doesn’t send at all. A fixture that invents its own response can never fail. Every test built on it was green and meaningless.
The check: fixtures get asserted against a recorded real response, and the builder rejects unknown keys. The suite that replaced it has 251 tests, and none of them can carry a field the API doesn’t send. If you let AI write your tests, as I do, check the fixtures too.
The common thread
None of these crashed. Every one of them returned something shaped like a correct answer. The model downstream did exactly what it was told with bad input, and the output looked as polished as it always does.
Here they are side by side.
| What the tool returned | The check we added |
|---|---|
| 1. A teammate’s name as a software company | Match names against the roster and project list |
| 2. April’s notes for a September meeting | Hash notes exports, reject repeats with a new date |
| 3. A new thread ID for an old conversation | Also match subject, people and first message |
| 4. Two clients’ work in one call | Name and drop items for other clients |
| 5. A contractor log missing July 4 | Bigger model, reconcile with the raw log first |
| 6. “No owed replies” from a broken search | Probe the query, fall back, say so |
| 7. 404 from 19 of 36 databases | Split “failed this run” from “unreachable” |
| 8. A dead login every day | Detect it, make re-auth one click |
What fixed them was always a comparison against something independent: a roster, a stored hash, a second matching key, a raw source, a probe query. The brain can’t tell a wrong input from a right one by looking at it, so each source needs one cheap check that doesn’t trust the source.
When someone shows you a company brain demo, ask what happens when the transcription mishears a name. If the answer is “the model will figure it out,” it won’t. We wrote each of these down as a learning so the next run, and the next engineer, starts from the check instead of the incident. By October 6 the learnings store held 41 entries. More on that habit in Write Down the Rulings, and on the system these checks protect in the pillar post on our company brain.
If you want Claude set up with these checks already in it, the setup starts at $3,997 for one team of up to 20. One job live on your real work by day 14, or all your money back.