Two Bots Argued on a Pull Request for 21 Hours
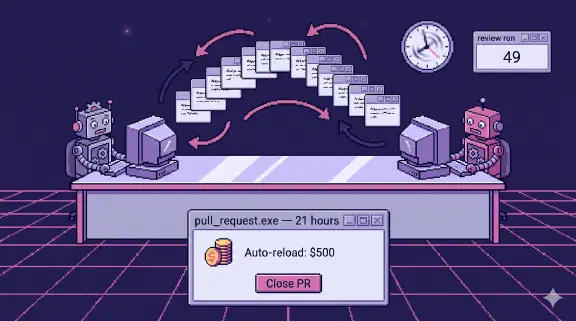
On the night of July 31, one of our scheduled AI routines opened a pull request, and our AI code reviewer left comments on it. The routine fixed what the reviewer flagged and pushed. The push triggered a new review. The new review found something else. They kept going for about 21 hours, through 147 review runs, and the bill showed up as roughly $500 in automatic credit reloads on our API account. Neither bot was broken. Each one did its job, and that’s why it took a day to stop.
The setup
Our company brain runs a handful of headless routines on a schedule. These are Claude Code sessions with no human in the chair. One of them, the nightly repo routine, does a repo-only slice of our end-of-day process: it checks whether summary docs have drifted from their sources, refreshes stale banners, writes a short report, and opens a PR with the changes.
Our main branch is protected. The one required check is an automated review: a GitHub Action that runs Claude against every PR and posts comments. Routines that produce mechanical output (index regeneration, banners, reports) are allowed to auto-merge once that review passes. Auto-merge with the wrong check in front of it caused a worse problem later, the day 46 confidential transcripts reached main.
The intended flow was simple. The routine opens a PR, the reviewer looks at it, the PR merges, everyone goes to sleep.
Two settings made it a loop. The reviewer ran on every push to a PR, which is a sensible default for PRs written by people. And nothing in the routine’s prompt told it to ignore review feedback, which is also sensible, right up until the reviewer is another model that will always find one more thing to say.
How it played out
A model reviewing a diff almost never says “this is perfect.” It’ll suggest a clearer phrase, flag a date format, question a heading. A model responding to that review almost never says “I disagree, leaving it.” It makes the change and pushes.
Every push re-fired the review. Every review cost a metered model run. By the end, that one PR had 148 commits on it, and each review ran for somewhere between 4 and 19 minutes. The routine session was still alive and still dutifully addressing comments. Nothing in either system had a notion of “we’ve been at this for six hours, maybe stop.”
An unrelated rule ended it. Each routine closes its own still-open PRs from previous nights before opening a new one, so PRs don’t pile up. The next night’s run started, saw the old PR still open, and closed it. That’s the only reason it was 21 hours and not a week.
Show the data
| What | Count |
|---|---|
| Review runs on the PR | 147 |
| Commits on the PR | 148 |
| First review to last | about 21 hours |
| Length of one review run | 4 to 19 minutes |
The part that stung more than the $500: we had a rule that routines must never call a paid model API. The routine obeyed it. It never touched an API key. The spend happened one hop away, in the reviewer it kept waking up. A cost rule that only looks at what a process calls directly misses every cost that process can cause downstream.
How to stop the Claude Code action reviewing every push
We fixed it from the reviewer’s side and the routine’s side, on purpose. Either fix alone would have stopped this incident. Having both means the next variation has to get past two guards.
The reviewer stopped reacting to routine pushes. PRs from routine/* branches got reviewed once when opened, never on later pushes. Dependabot bumps and PRs with 30 or more commits were skipped entirely. A per-PR concurrency group collapses a burst of pushes into a single review run instead of one per push. One detail we had to check: when the review job skips itself, GitHub reports it as “skipped,” and GitHub’s docs say a skipped job reports success and won’t block a merge even when it’s a required check, so auto-merge keeps working.
The routine stopped arguing. A new rule went into the output convention every routine follows: once the PR is open, the run is complete. At most one correction push, and only if the reviewer found a genuine factual error. All further review comments are ignored. The rule includes the incident date and the run count (it says 49+, which turned out to be an undercount; GitHub’s run history for the PR shows 147), so anyone who later wonders why it’s there can see the reason without digging through git history.
Only mechanical routines auto-merge. Routines whose output is derived and idempotent (regenerated indexes, banners, health reports) can merge on a passing review. Anything involving judgment, like a content sync or a security scan, leaves the PR open for a person.
Spend became visible. Our weekly review now has a “metered spend, month to date” line pulled from the API console. If the admin key that reads it isn’t configured, the line prints “not measurable” instead of disappearing. A missing line looks like zero spend. An explicit “not measurable” looks like a gap someone should fix. We ended up applying that rule to every line in the weekly review, after three feedback loops collected nothing for two months.
The follow-up review found more
A few days later we went back over the review workflow with fresh eyes, and the incident turned out to be the least embarrassing thing in it.
First, nobody was reading the one review that routine PRs still got on open. An automation nobody reads is the kind I now question before building it at all. So we dropped reviews on machine-authored PRs entirely: anything from a bot account, plus our routine branches, which push under a human account and would slip past a simple bot check.
Second, the reviewer had been pinned to a specific model since mid-March. That pin never took effect. The action doesn’t have a model input at all (its input list has none). It had been printing an “Unexpected input” warning on every single run for almost five months, and every review in that time ran on whatever the action’s default was. We moved the pin to claude_args, the CLI argument passthrough the action actually documents.
Third, the workflow granted write access to the repository at the top level, which applied to both jobs. The review job only needs to post comments, but because of that grant, it could have pushed code. Each job now declares its own minimum permissions, which is what GitHub recommends for the workflow token anyway.
None of that caused the loop. All of it had been sitting there quietly, and we only found it because the loop made us look.
Here’s the review job as it runs today, trimmed from our workflow file. Every pull request gets one review when it opens or leaves draft, never on a push. Our real file also has a second job that answers @claude mentions, which is how a person asks for another pass.
name: Claude Code

# No workflow-level grants. Anything set here applies to every job,
# and the reviewer only needs to comment.
permissions: {}

on:
  # Review once when a PR opens or leaves draft, not on every push.
  pull_request:
    types: [opened, ready_for_review]

jobs:
  claude-review:
    # Skip machine-authored PRs. Bot accounts have user.type "Bot".
    # Our routines push routine/* branches under a human account,
    # so they need the branch-prefix check. PRs past 30 commits
    # are too big to review usefully.
    if: |
      github.event.pull_request.user.type != 'Bot' &&
      !startsWith(github.event.pull_request.head.ref, 'routine/') &&
      github.event.pull_request.commits < 30
    permissions:
      contents: read        # the reviewer comments; it never pushes
      pull-requests: write
      issues: write         # `gh pr comment` posts through the issues endpoint
      id-token: write       # the action fetches an OIDC token on every run
    concurrency:
      group: claude-review-pr-${{ github.event.pull_request.number }}
      cancel-in-progress: true
    timeout-minutes: 20
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v7
        with:
          fetch-depth: 1

      - uses: anthropics/claude-code-action@v1
        with:
          # Subscription token from `claude setup-token`
          claude_code_oauth_token: ${{ secrets.CLAUDE_CODE_OAUTH_TOKEN }}
          prompt: |
            REPO: ${{ github.repository }}
            PR NUMBER: ${{ github.event.pull_request.number }}

            Review this pull request following the guidelines in REVIEW.md.
            Use `gh pr comment` for top-level feedback.
            Only post GitHub comments.
          # The model goes here. The action has no `model` input.
          claude_args: |
            --model claude-sonnet-5 --allowedTools "mcp__github_inline_comment__create_inline_comment,Bash(gh pr comment:*),Bash(gh pr diff:*),Bash(gh pr view:*)"
Two details are easy to miss. The skip has to be a job-level if:, never a filter under on:. A skipped job still reports a conclusion that satisfies the required check, while a workflow that never runs reports nothing and leaves every automated PR blocked forever. And id-token: write is required even with a static token, because the action fetches an OIDC token on every run and fails with “Could not fetch an OIDC token” without it.
Cost guards one hop out
The same month, we found our own test suite had been billing a metered API key on every run. Six tests called an LLM scoring function without mocking it, and the test process inherited the real key from the environment. The fix was a tripwire that strips model API keys from every test that isn’t explicitly marked as needing the network, plus two tests that make sure the tripwire itself can’t quietly stop working. The suite got about a minute faster, and no test turned out to need a live key.
In September we rewrote the “never call a paid model API” rule completely. The new version allows paid APIs when they do the job better, with conditions: every call site gets registered, it falls back to the session if the API fails, it stays advisory at any human approval step, it gets shadow-tested against our own past decisions first, and it reports its cost. The old rule was a ban that looked strict and missed the actual spend. The new one is permissive and asks every call to show up somewhere a person will see it.
What I’d take from this
When two automated systems talk to each other, assume one of them will never say “done.” Models are agreeable, and two agreeable models in a loop will happily agree with each other until something external stops them. Deciding when to stop is exactly where models are weakest, which I wrote about as the control flow problem. Put a hard cap on the number of turns, put it in more than one place, and make sure the cap doesn’t depend on either model deciding to stop.
And watch the costs your automation causes downstream as well as the ones it incurs directly. Our routine had a spotless record on API calls and still ran up a $500 night.
This is one piece of a bigger system. The pillar post covers the rest of it, and our Claude Code team setup shows how the shared settings and commands reach everyone. If you’re running Claude Code headless and want a second pair of eyes on your guardrails before your own $500 night, I do coaching on your repo. Build It Yourself coaching is four 90-minute sessions for $1,997.