Two Founders, One Company Brain, and the Duplicate Problem
My co-founder and I each run an AI end-of-day process on our own inbox and calendar, and most of our client meetings and threads include both of us. Left alone, two runs means every transcript gets filed twice and every action item becomes two tasks. Getting two runs to share one brain took a shared table, two kinds of keys, and one rule about owed replies that turned out to matter more than the rest.
Personal AI setups never hit this problem, because there’s only one person. It shows up the moment a second person points the same system at their own mail.
The setup
Our company brain is a git repository with a folder per client (how it’s built). Each founder ends the day by running /strategy:day-end-process. It reads that founder’s meetings and email from the day, files transcripts and email syntheses into the right client folder, drafts replies, proposes tasks and suggests doc edits.
Each run keeps its own ledger, so my run knows what my previous runs did. It had no idea what my co-founder’s run did. When we both sat in the same client call, both runs would file the transcript and both would extract the same five action items into the shared task tracker. The task tracker already had its own problems with volume (1,042 tasks in four months), and duplicates across founders made them worse.
A shared coverage table
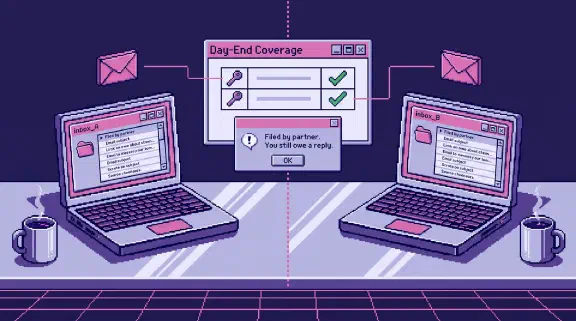
On June 24 we added a Notion database called “Day-End Coverage.” When a run finishes, it records every source it processed. When the other founder’s run starts, it reads that table first and skips filing anything already covered. It reads live from Notion instead of from git, because the two runs happen on different machines at different times and a git-based record would always be one pull behind.
The overlap is large. On my September 2 run, 15 of the 42 email threads it reviewed were already covered by my co-founder’s run.
The hard part was the key. You need an identifier for “this email” or “this meeting” that comes out identical from two different accounts.
Email. Gmail thread IDs are scoped to the mailbox. My thread ID for a conversation and my co-founder’s thread ID for the same conversation are unrelated strings. What does survive across mailboxes is the RFC822 Message-ID of the first message, which every reply carries forward in its References header (RFC 5322 spells out how each reply copies its parent’s chain). So the key is email:<root Message-ID>. Two details make this harder than it sounds. Message-IDs are case-sensitive, so the code never lowercases them. And Gmail sometimes merges two separate conversations into one thread when the subjects match (its API docs list a matching Subject header as one of the threading rules), so a thread can contain more than one root. The script picks the most common root as the key and stores all of them.
Meetings. Calendar events have an iCal UID that’s shared across attendees, which looks perfect until you hit a recurring meeting. Every occurrence of a weekly call shares the same UID. That’s by design: the iCalendar standard (RFC 5545) refers to a whole recurring series by one UID, and Google’s Calendar API reference says outright that all occurrences “share the same iCalUIDs.” So the key is the UID plus the start time: meeting:<iCalUID>:<start>. Later we found that a meeting rescheduled by a few minutes got a new key and slipped past coverage, so meetings now also match on a day-level alias (UID plus date).
All of this lives in one small, pure Python module with 22 tests covering cases like merged Gmail threads, missing Message-IDs, recurring occurrences and the same instant written in two time zones. The keys are computed by a script, never typed by the model. An LLM asked to copy a long Message-ID will eventually get one character wrong, and a wrong key fails silently.
The rule that mattered most
The obvious design is to hide anything my co-founder already processed. We wrote a rule against that into the very first version.
My co-founder filing a client email into the repo does nothing about the fact that the client asked me a question. If I’m on the To: line and I owe a reply, I still owe it. So the coverage table has a hard rule, written into the command as an invariant (a rule the AI has to follow belongs in writing, which is also why we keep a log of rulings): coverage only stops a source from being filed again. It never removes a thread from my owed-replies list, and it never suppresses a meeting that has no transcript yet (a late transcript still has to get processed on a later run).
We still got this wrong once, and didn’t fix it until September. An earlier version of the meeting step skipped all processing for a meeting my partner had already saved. Saving the transcript is only one of five things that step does. It also extracts my tasks, completion signals, unblocks and doc-change signals. So for any meeting a colleague happened to save first, four of those five went missing, with no error. The fix was to split it: if my partner saved it, skip the export and still run the extraction. If my own earlier run processed it, skip everything, because re-processing would mint duplicate drafts.
Failing in the right direction
Every coordination system has to decide what happens when coordination breaks. Ours fails open. If Notion is down, the database isn’t shared with the integration, or the API errors, the run gets empty skip lists, prints a warning and processes everything.
That choice comes from comparing the two failure modes. A miss costs a duplicate, and duplicates are annoying but visible. A per-owner task deduper and idempotent writes catch most of them downstream. Over-suppression costs a dropped obligation, which is invisible until a client follows up asking why nobody answered. A system that can only fail by doing extra work is one you can leave running.
What else broke
The first version wrote one row per source. A 13-day catch-up run wrote 86 rows by itself, which is a lot to scroll through when you just want to know what your partner covered. In July we moved to one row per founder per run day, with the source keys in a JSON document on the page and a readable table of sources mirrored next to it.
Runs also get interrupted. A run can stop at the approval step with tasks not yet created, and coverage written at that point would tell the other founder’s run to skip sources whose tasks don’t exist yet. Now a run records a provisional checkpoint row, and the other founder’s run prints a warning naming whose run is stalled and on which date.
Then a third writer showed up. In September we added an hourly job that ingests transcripts automatically. It isn’t a founder and doesn’t write coverage rows, so it was invisible to the table. Its transcripts carry a source_key: header in the file, and the day-end run checks for that before writing. The coverage script’s own test file grew alongside each of these fixes and is now at 41 tests.
Where this applies beyond two founders
Two account managers copied on the same client thread will hit this in their first week. The details that matter carry over: pick keys that are stable across accounts, compute them with code, decide which failure you’d rather have, and never let “someone else filed it” mean “someone else answered it.”
The email side of this, including how each person’s mailbox gets connected, is in Can Claude Read My Email?. The end-of-day run that does the filing, and how it compares with Anthropic’s Claude Duet, is in Claude Code as a Chief of Staff.
If you and a co-founder are the ones answering every question about every client, this is the page I wrote for you. I’ll teach you to build one yourself, or build it for you in 14 days.