Write Down the Rulings
Oct 16, 2026 · 6 min read
When we started logging our company’s rulings in July, six of the first ones were copied out of one person’s private AI memory files. One of them was the rule that the AI never sends client email on its own. It had been quietly governing that person’s Claude sessions and nobody else’s. This post is about the log we built to fix that, and about the other knowledge that disappears when people leave. It’s the part of our company brain I’d build first if I were starting over.
By “ruling” I mean a decision that constrains future work. How we price a certain kind of project, what a retainer covers, when work is allowed to start, what happens to a client’s infrastructure if they stop paying. These get made constantly, usually on a call, and then live in someone’s head.
Where our rulings used to live
Before July, a ruling could be in any of four places. Claude Code’s per-user memory, which only that user’s sessions read. A client’s MEMORY.md, written as prose and mixed in with relationship notes. A meeting transcript, if someone remembered which meeting. Or nowhere, in which case it lived in whoever was on the call.
This mostly works while the people who made the decisions are the ones doing the work. It fails in two predictable ways. A proposal gets drafted against a rule that was changed three weeks ago, because the AI drafting it read an old memory file. Or someone new asks “why do we do it this way?” and nobody can answer with anything better than “I think we decided that in the spring.”
One log, append-only
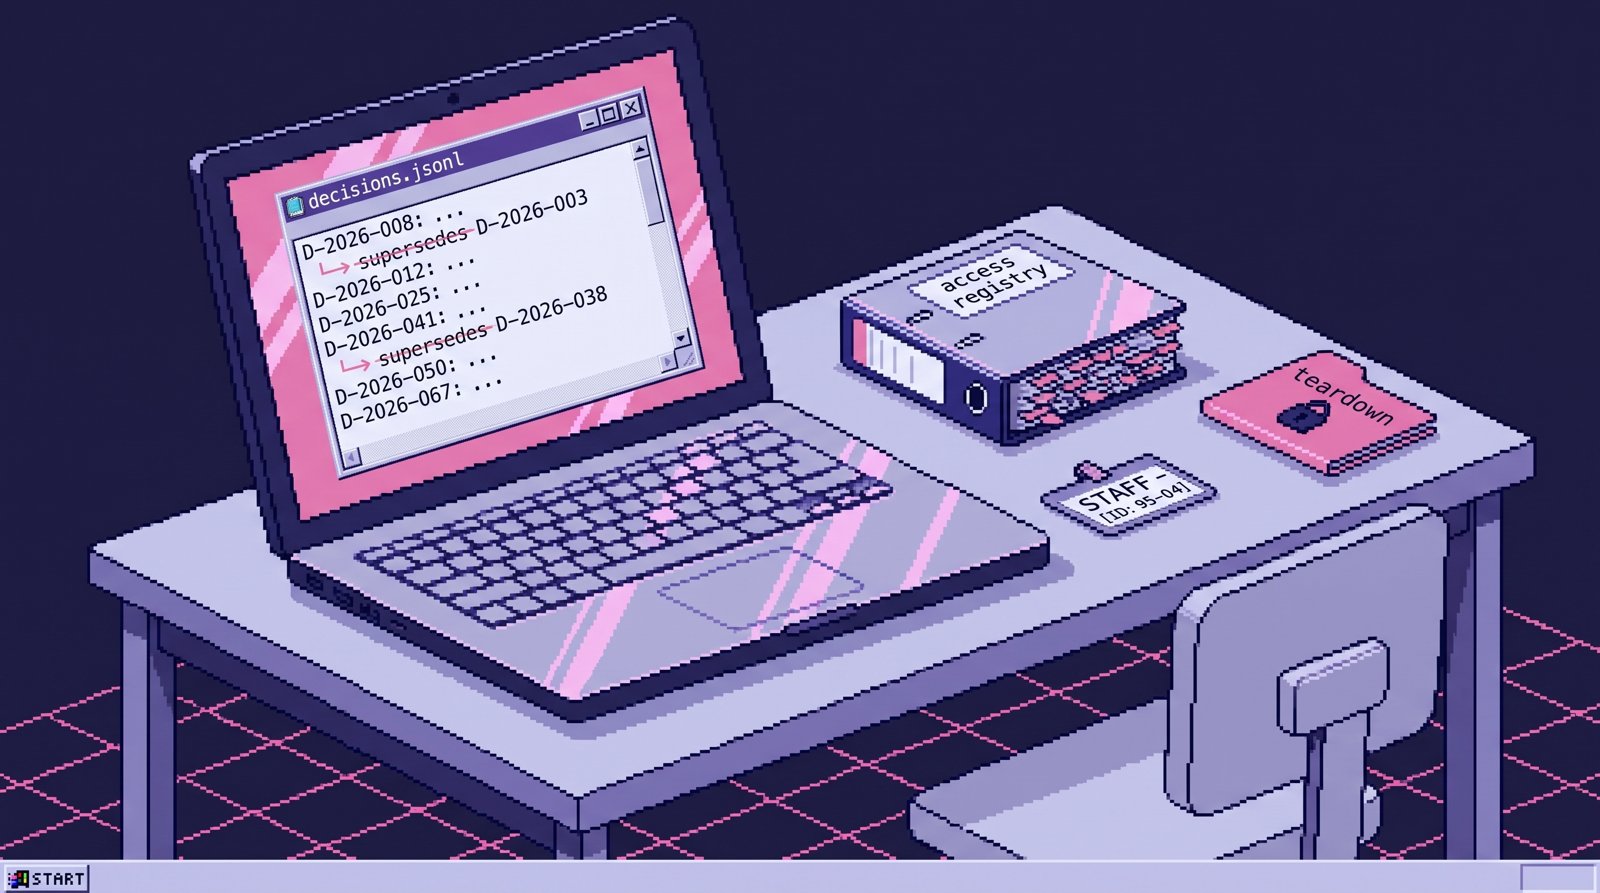
The fix is a single file, strategy/decisions/decisions.jsonl, tracked in git. One ruling per line, each with an ID like D-2026-008, a date, the decision in a sentence or two, the rationale, a scope (the whole company, one client, or one engagement), an owner and a supersedes field.
Rows are never edited and never deleted. When a ruling changes, we append a new row that names the row it replaces. The old one stays in the file, marked inactive when the projection gets generated. A machine-owned decisions.active.md shows only the current set, grouped by scope, and no human edits it.
That rule sounds fussy until you need it. When a pricing ruling from early July was replaced in September, the log kept both versions: what we used to do, what we do now, the date, and why. If a client asks why their quote differs from one they got in the summer, both answers are in the same file, and the newer row points at the older one.
The log has 42 rows today. Five have been superseded by later rows. 36 are company-wide, five apply to one client, and one applies to a single engagement.
Rulings have to reach the work
A log nobody reads is a diary. The rulings matter because the commands that produce estimates, proposals, statements of work and engagement letters load the active set, filter it by scope and print a line like this for every ruling that applies:
Active decision applies: <the ruling, in one sentence> (D-2026-0NN, <date>)
That line ends up in the working document, so the human reviewing a proposal can see which rules shaped it. As of this week, 28 documents across client folders carry at least one of those lines. When a ruling changes, the next proposal picks up the new one without anyone needing to remember.
Write down the exceptions too
Real policies have exceptions, and a log that pretends otherwise gets ignored. Several of our rows are explicit one-client exceptions: a single engagement allowed a pricing structure that the company-wide rule forbids, or a partner given a rate below the published one. Each of those rows names the general rule it’s an exception to and is scoped to that one client, so it never leaks into anyone else’s proposal.
Unwritten exceptions are how rules drift. Someone remembers that “we did it differently for that one client” and generalizes it, or forgets the exception exists and quotes the wrong number to the client who has it.
The log had a bug, and the bug was useful
IDs are sequential and assigned when a row is written. In early October four rulings were logged on a working branch as D-2026-037 through 040. Meanwhile main had already assigned 037 and 041 to other rulings. Merging would have produced two different rulings sharing an ID. We caught it at merge, renumbered the four to 038, 039, 040 and 042, and fixed the citations in the docs that referenced them.
Our learnings store, which uses the same append-only design, has the same scar: one learning ID was issued twice. Neither caused damage we know of, and both were easy to untangle because both stores are plain text in git and the history shows exactly what happened. I’d take that over a database that silently resolves the conflict for me.
Lessons travel with a safety flag
Rulings are what we decided. Learnings are what we found out, like the fact that AI-created tasks go stale within about two days and start duplicating (the lesson behind how we cut task volume). They live in a separate store with one field the rulings log doesn’t need: client_safe. A lesson learned on one client’s project never shows up in another client’s materials unless it has been rewritten without identifying detail. Of 42 learnings so far, 33 are marked safe and 9 are not.
A few more rules keep the store from turning to mush. A pattern only becomes a rule after three or more confirmations. Changes to skills arrive as proposed diffs that a human merges. And nothing is allowed to re-summarize the store wholesale, because each AI summary pass loses a little detail and after a few of them you’re left with platitudes.
Access is a ruling too
The other knowledge that walks out the door is who has access to what. Our repo keeps an access registry: 40 pages, one per platform, listing who has access, MFA status and cost tier. The root CLAUDE.md tells Claude to ask about updating it whenever a new tool, account or credential comes up in conversation.
We learned why the hard way. When a contractor left in June, we ran a live audit of our Google Cloud organization across 58 projects. It found about 15 projects nobody had documented, and a team member’s personal Gmail account still holding access to production. When two more contractors left this month, the offboarding was a pass through the registry, checked against each platform’s live console: nine platforms, eight cloud projects only they owned handed to someone else, five empty ones deleted. The registry had drifted too. One platform’s page listed the roster from a completely different platform.
Teardowns follow a written rule
The same pattern applies when a client relationship ends badly. In September a client stopped paying and stopped responding. Their system was still running on infrastructure we hosted, including a nightly job syncing their records, which meant we were holding more of their data every night and not getting paid for it.
The obvious move is to back up the database and delete the project. The backup nearly shipped incomplete. The standard database dump doesn’t include the source code of the serverless functions, and those functions were the entire data pipeline. We only caught it because someone audited the dump before deleting anything.
That teardown became ruling D-2026-025: back up first, prove the backup actually restores (a structural check doesn’t count), capture whatever the dump leaves out, and log the teardown in the access registry. The next person who has to do this won’t need to have been there.
What I’d tell another team
Start with a single file and the discipline to append instead of edit. Put the rulings where your tools read them, so they show up in the work instead of in a wiki nobody opens. Write down exceptions as their own rows. Keep a page per platform for access. None of it is technically hard. The hard part is doing it while the decision is fresh, which is why we wired it into the end-of-day and end-of-week commands instead of trusting anyone’s memory, including mine.
The rulings log and the access registry are the parts of our brain that would survive any one of us leaving. If you want that for your team, I build company brains in 14 days.
More Thoughts
Before Automating Something, Ask Whether It Should Exist
Oct 16, 2026 · 6 min read
The first verdict our build gate ever gave was DON'T, for a vacation reminder job. It got the right answer by asking the …
Read more
Eight Small Ways Our Tools Lied to the Brain
Oct 16, 2026 · 5 min read
The tools feeding our company brain broke it more often than the model did: transcription, email, notes and auth kept …
Read more
Our AI Created 1,042 Tasks in Four Months
Oct 16, 2026 · 6 min read
Between June and September our company brain created 1,042 tasks from our email and meetings. Most of them were noise. …
Read more
Our AI Drafts Every Email and Sends None of Them
Oct 16, 2026 · 5 min read
In four months our company brain surfaced 626 email threads where we owed a reply, and it can draft any of them. It …
Read more